Pretrained world models predict the consequences of alternative actions, improving fully decentralized on-policy multi-agent learning.
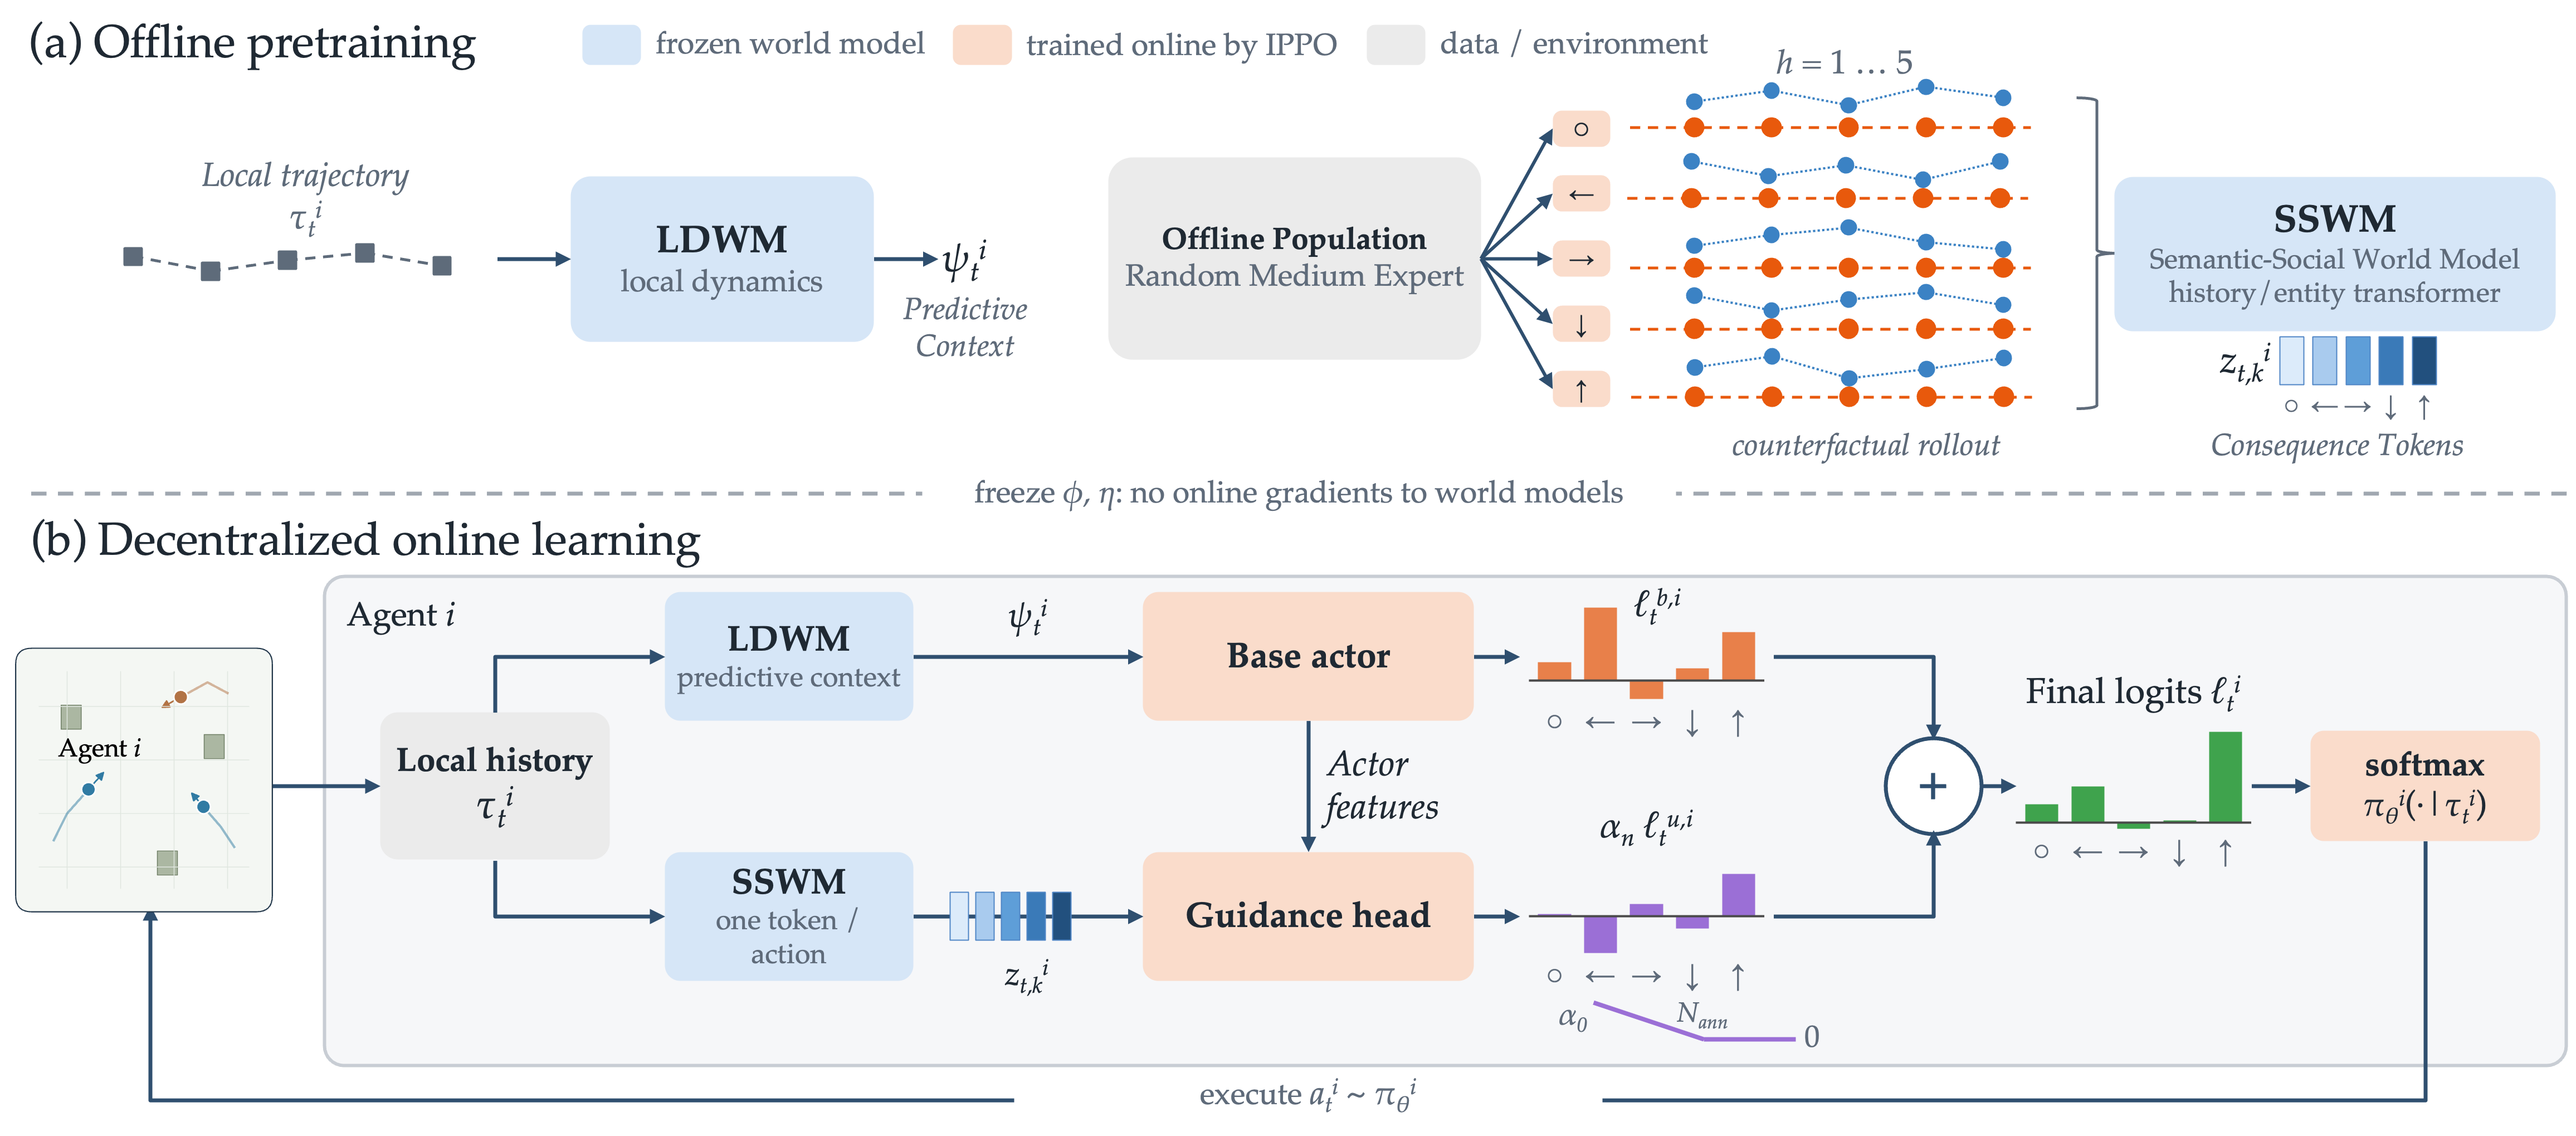
Overview
CASTLE uses two complementary world models: one captures local dynamics, and the other predicts task and social consequences for each candidate action. The models are trained offline, then held fixed while each agent learns from its own local experience using independent PPO.
This is a public preprint submitted for review.